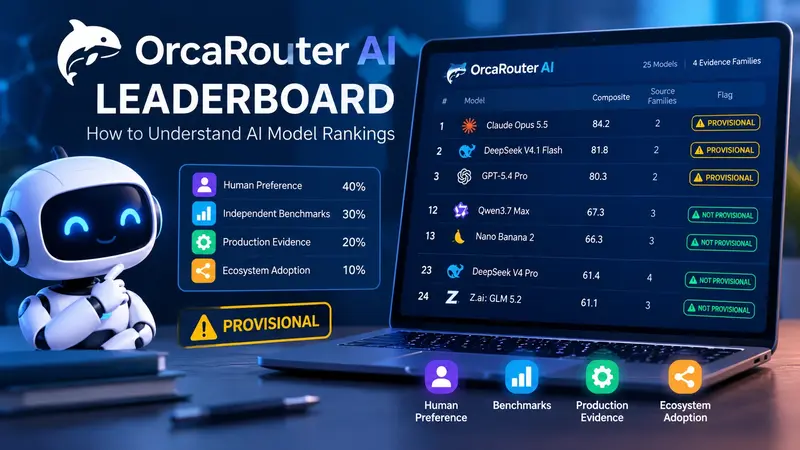
The OrcaRouter AI leaderboard lists twenty-five models with a composite score, and twenty-one of them carry a provisional flag [OURS, page data read 2026-10-21].
Four do not. The distinction is not cosmetic, and it is the first thing to check before quoting a position from this board.
What the flags encode
The board’s methodology says a model needs at least two independent evidence families to rank at all, and the composite is built from four: human preference weighted 40 percent, independent benchmarks 30 percent, production evidence 20 percent, and ecosystem adoption 10 percent [OURS].
The source counts on the twenty-five rows distribute as two families on eighteen rows, three on six, four on one [OURS]. The single four-family row is DeepSeek V4 Pro, ranked 23rd.
So “provisional” is not a flag about data quality in the abstract. It means the rank was computed from the minimum number of families the board will accept. Eighteen of the twenty-five sit at that minimum, which means the board is largely populated by models scored from two signals out of four.
That is not a defect. A leaderboard that only admitted fully-measured models would list four rows and answer nobody’s question. But it does mean the number at the top of the page is a blend of a blend, and the thinner the underlying evidence, the less the position should be treated as a stable fact.
The four that are not provisional
| Rank | Model | Composite | Source families |
| 12 | Qwen3.7 Max (2026-05-20) | 67.3 | 3 |
| 13 | Nano Banana 2 (Gemini 3.1 Flash Image Preview) | 66.3 | 3 |
| 23 | DeepSeek V4 Pro | 61.4 | 4 |
| 24 | Z.ai: GLM 5.2 | 61.1 | 3 |
Four rows, and their reason for being non-provisional is visible in the last column: three families or more. The one four-family row is the least provisional entry on the board, and it sits at rank 23 — a fact worth sitting with, because it inverts the usual assumption that better-documented models rank higher.
There is a second pattern in that table. The four non-provisional rows are not the top four. They are ranks 12, 13, 23 and 24 — a spread across the middle and the bottom of the board. The top three rows are all provisional, each scored from two families.
That is what a board built from public evidence looks like in practice. The newest and strongest models have the least accumulated evidence because they haven’t been in production long enough for the third and fourth families to report.
Why the flagship rows are provisional
Look at what the top rows are missing.
The first-place row, Claude Opus 5.5 at 84.2, carries two signals: an independent benchmark index and an adoption share [OURS]. The second-place row, DeepSeek V4.1 Flash at 81.8, carries the same two. The third, GPT-5.4 Pro at 80.3, carries an independent benchmark index and a production win rate.
So the top of the board is a blend of a benchmark score and one other thing — and the other thing differs between rows. One row’s second family is an adoption share, another’s is a win rate. Those are not the same measurement, and a reader comparing rank 1 with rank 3 is comparing two different blends that happen to share a scale.
The board is explicit that this is by design: new models enter from external evidence within 48 hours of release, and no self-reported vendor numbers are used anywhere. The trade-off is that a model which has just launched gets a rank before it has traffic, and its position is a projection rather than an observation.
What a two-family rank is worth
The practical question is how much weight to put on a provisional position, and the answer depends on which two families are behind it.
A benchmark index plus an adoption share describes a model that scores well and is used. Those two signals can disagree — a high benchmark and low adoption is a common pattern for a new release — and when they do, the composite splits the difference in ways the weights determine rather than the data.
A benchmark index plus a win rate describes a model that scores well and wins head-to-head comparisons on this platform. That pairing is stronger for judging quality because both signals measure capability rather than popularity.
Two benchmark families would be the strongest pairing of all, and no row on the board currently has it.
A reader who quotes “rank 2” without the flag is quoting a blend of an independent index and an adoption share as though it were a capability ranking. On a board where eighteen of twenty-five rows rest on two families, that is the rule rather than the exception — and it is why the board prints the flag in the first place.
The weights are public, which is the real feature
Whatever a reader thinks of the ranking, the mechanism is unusually visible: the four weights are fixed and published, the normalization is described — each signal is standardized against the current board, mapped to 0–100 with 50 as the average and every 15 points as one standard deviation, clamped at the extremes — and the board states that popularity and sentiment are context only and never affect rank [OURS].
That combination is what makes the provisional flag usable rather than decorative. Because the weights are known, a reader can recompute a rank under different weights and see how sensitive it is. A model ranked second on a blend that is 40 percent human preference would rank differently on a blend that weighted benchmarks more heavily, and the board’s own published weights make that arithmetic possible.
The alternative — a board that publishes a rank and hides the recipe — gives a reader no way to check whether the position means what they think it means. This one gives them the recipe and a flag telling them how much of it was actually available.
How to read a provisional rank
Four rules.
Check the flag before the number. A rank with two families behind it is a projection. A rank with four is a measurement. They appear in the same column and are not the same kind of claim.
Check which families. The board does not print the family names in the table, but the underlying data carries them, and a benchmark-plus-adoption blend is not the same thing as a benchmark-plus-win-rate blend.
Do not compare ranks across a family change. A model that gains a third source can move without changing at all, because the blend it sits in changed. Any movement worth reporting should be checked against the source count first.
Treat the top of the board as the least settled part. The newest models rank highest and carry the thinnest evidence. That is what a 48-hour entry rule produces, and it is a feature for freshness and a hazard for anyone quoting positions as facts.
A leaderboard’s job is to compress several kinds of evidence into one number. This one tells you how many kinds went into each row, which is more than most do, and the twenty-one flags are the most useful column on the page. Learn more about Technology.
Final Thoughts
The OrcaRouter AI leaderboard offers a useful way to compare AI models, but understanding the evidence behind each ranking is just as important as looking at the final score. Provisional flags help readers identify models based on fewer evidence sources, while the published scoring methodology provides greater transparency into how rankings are calculated.
Rather than treating every position as a definitive measure of AI capability, readers should consider the number and type of evidence families supporting each model. As newer models accumulate more performance data, their rankings may become more reliable and easier to compare. Ultimately, the OrcaRouter AI leaderboard is most valuable when its scores are viewed as informed comparisons rather than absolute judgments of model quality.